Why Product Specifications Matter in eCommerce
12 Aug 2026
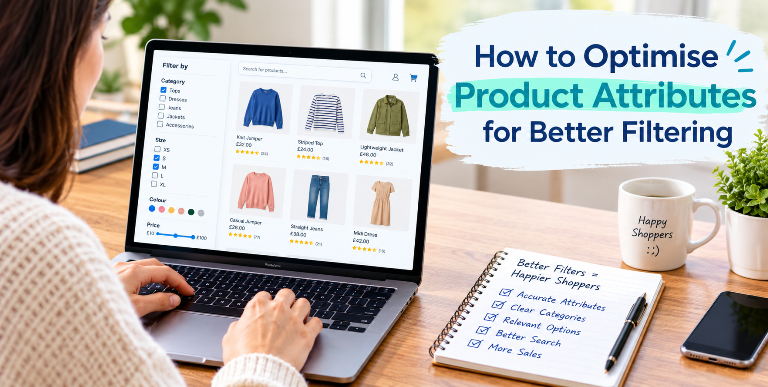
A shopper searches for a pair of running shoes and selects Size: 9, Colour: Black, Brand: Nike.The catalog contains the right products. The website has filters. The search system is working.
Yet several relevant products disappear from the results.
The problem may not be the filter itself.
It may be the product data behind it.
This happens more often than ecommerce teams expect. One product may have its colour recorded as Black, another as black, another as Jet Black, and another as Black/White. From a customer’s perspective, these may be perfectly understandable descriptions. From a filtering system’s perspective, they can be completely different values.
Product attributes sit quietly underneath the storefront, but they influence how shoppers browse, filter, compare, search, and discover products.
For catalogs with a few hundred SKUs, inconsistent attributes can be annoying. For catalogs containing tens of thousands of products across Shopify, Amazon, marketplaces, and internal systems, they can become a serious merchandising problem.
The good news is that improving product attributes does not always require rebuilding the entire catalog. A structured cleanup process can make filtering considerably more reliable.
A product title tells shoppers what an item is.
Attributes help them decide whether it is the right item.
Consider a furniture store selling 8,000 products.
A customer might want:
If those values are stored consistently, the customer can narrow thousands of products to a manageable selection.
But suppose the catalog contains:
Some of these values describe similar concepts, while others represent genuinely different materials.
If the attribute structure has not been planned properly, the filtering experience starts breaking down.
This is why attribute optimization is not simply a matter of filling in more product fields. It involves deciding which attributes matter, how they should be represented, and how values should remain consistent across the catalog.
One of the first mistakes we see in catalog work is treating product descriptions as a substitute for structured attributes.
A description might say:
This lightweight cotton shirt features a regular fit and is available in classic navy blue.
That sounds useful to a shopper.
But if Material, Fit, and Colour are empty fields, a filter may have no reliable data to work with.
The same information should ideally exist in structured fields:
| Attribute | Value |
|---|---|
| Material | Cotton |
| Fit | Regular |
| Colour | Navy Blue |
The description can still explain the product naturally. The attributes give the ecommerce system usable data.
This distinction becomes particularly important when products are imported from suppliers. Supplier spreadsheets often contain useful information, but it may be buried inside titles, descriptions, specifications, or inconsistent columns.
The catalog team’s job is to turn that raw information into structured, usable product data.
Cleaning thousands of attribute values without defining the rules first usually creates another mess.
Start with the product category.
A fashion catalog might require:
A laptop catalog could require:
A furniture catalog might rely on:
There is no universal list of “best” attributes.
The right structure depends on what shoppers actually use to distinguish products within a category.
If an attribute helps a shopper meaningfully narrow a category, it deserves consideration as a filter.
If an attribute is rarely populated, difficult to standardize, or does not help customers make a selection, making it a filter may create more clutter than value.
Having a column called Colour does not mean the color data is ready for filtering.
Imagine a catalog containing these values:
A human can understand most of these.
A database does not interpret them the same way unless rules have been established.
A sensible normalization process might include:
Step 1: Identify duplicates
Find values that mean the same thing but are written differently.
Step 2: Create an approved value list
For example:
Step 3: Map inconsistent source values
Step 4: Preserve meaningful distinctions
Do not blindly merge every similar value.
“Black” and “Black/White” may need to remain separate if customers genuinely use them differently.
That last point matters.
Over-normalization can be just as harmful as inconsistent data.
A product attribute is valuable when it reflects a real shopping decision.
Take a mobile phone category.
A shopper might filter by:
A field such as Internal Product Code may be essential for warehouse operations but almost useless as a customer-facing filter.
This distinction is important when designing an ecommerce catalog.
You may have dozens of attributes in your backend. That does not mean shoppers should see dozens of filters.
A useful approach is to classify attributes into three groups:
These directly help shoppers narrow products.
Useful on the product page but not necessarily appropriate as a filter.
Important for inventory, fulfillment, accounting, or internal workflows but generally hidden from customers.
This keeps the filtering experience focused.
Free-text fields are convenient when products are being uploaded quickly.
They are also a common source of catalog inconsistency.
For example, if a supplier enters the product type manually, you might eventually see:
If these are intended to represent the same category, the filtering and categorization system has unnecessary variation.
Controlled vocabularies reduce this problem.
Instead of allowing every uploader to enter a new value, provide an approved list.
For example:
Product Type
This becomes especially valuable when multiple people are uploading products.
One person may write “Sneaker.” Another writes “Sneakers.” A third chooses “Sports Shoes.”
Without governance, the catalog slowly fragments.
Numeric attributes create another class of filtering problems.
Consider televisions.
One supplier may enter:
Another may enter:
All may describe approximately the same screen size.
If the platform expects a numeric field, storing these as inconsistent text values can make range filtering unreliable.
Where possible, establish:
For example, screen size might be stored as a numeric value in inches while the storefront displays it as 55 inches.
The same principle applies to:
The exact implementation depends on the ecommerce platform, but the underlying principle is the same: store data consistently before asking the filter system to interpret it.
This is a common source of confusion in fashion and other variant-heavy catalogs.
Suppose a T-shirt comes in:
and in:
Those attributes may belong to variants rather than simply being generic product-level information.
Now imagine a customer selects:
Colour: Navy
The store should ideally return products that actually have a Navy variant available—not products whose parent product happens to mention Navy somewhere in its description.
The same issue appears with:
When managing large catalogs, teams should decide carefully whether each attribute belongs at the product level or variant level.
Getting this wrong can create misleading filters.
If you have a large existing catalog, avoid attempting a random cleanup.
A controlled workflow is much safer.
Pull the relevant product fields into a working file or data-management environment.
Include:
Look for:
This first audit often reveals that the biggest problem is not missing data—it is inconsistent data.
Create category-specific rules.
For example:
Colour: Black, White, Navy, Grey, Red
Fit: Slim, Regular, Relaxed, Oversized
Material: Cotton, Linen, Polyester, Wool
The actual vocabulary should come from the products you sell and the way customers shop for them.
Create a transformation table.
| Existing Value | Standard Value |
|---|---|
| blk | Black |
| BLACK | Black |
| Black Colour | Black |
| navy blue | Navy |
| Blue Navy | Navy |
Do not automatically merge values that have different commercial meanings.
If a critical attribute is missing, identify whether the information exists elsewhere.
It may be found in:
This is where manual review can still be necessary.
Before publishing the cleaned catalog, check:
The cleanup is not finished when the existing catalog looks clean.
If new products continue entering the system with uncontrolled values, the same problem will return.
New product uploads should follow the same attribute rules from day one.
Managing one ecommerce store is challenging enough.
Managing the same products across Shopify, Amazon, eBay, Walmart, or regional marketplaces introduces another layer of complexity.
Different channels may use different:
The solution is not to maintain completely separate product information manually.
A better approach is to maintain a reliable source catalog and create controlled mappings for each destination.
This reduces unnecessary re-entry and makes future updates easier.
More filters do not automatically create a better shopping experience.
Too many options can overwhelm shoppers and make navigation harder.
If every team member creates their own attribute terminology, inconsistency is almost guaranteed.
“Black leather upper” inside a description does not replace structured values for colour and material.
A product-level value can create misleading filtering when availability differs by variant.
Inactive, unpublished, or older SKUs can contain bad values that resurface when products are reactivated.
Automatically changing every similar value can destroy meaningful distinctions.
Human review still matters when the difference affects how customers shop.
Before considering a catalog ready for better filtering, ask:
If several answers are “no,” the catalog probably has room for improvement.
Large-scale attribute cleanup can become surprisingly labor-intensive.
A 2,000-SKU catalog may be manageable internally. A 50,000-SKU catalog with multiple categories, variants, suppliers, and marketplaces is a different operational problem.
At that point, teams often split the work into:
At India Data Entry Services, we’ve worked with ecommerce catalogs where the challenge was not simply uploading products—it was making thousands of inconsistent product records usable across different sales channels.
The important part is having clear rules before the volume of data becomes difficult to control.
A filter is only as good as the attribute data behind it.
If the catalog contains inconsistent colours, incomplete sizes, mixed units, poorly assigned categories, or incorrect variant information, even a sophisticated ecommerce platform cannot completely compensate for the underlying data.
The most effective approach is therefore to treat product attributes as part of your catalog architecture—not as fields that get filled in at the end of a product upload.
Define the attribute structure.
Standardize the values.
Map supplier data carefully.
Separate product-level and variant-level information.
Validate before publishing.
Then keep the same rules in place for every new SKU.
For a small catalog, this may take a few disciplined working sessions. For a large catalog, it becomes an ongoing data-management process.
Either way, the objective is straightforward: when a shopper selects a filter, the products shown should genuinely match what they selected.
That is what turns product attributes from backend housekeeping into a better shopping experience.
12 Aug 2026