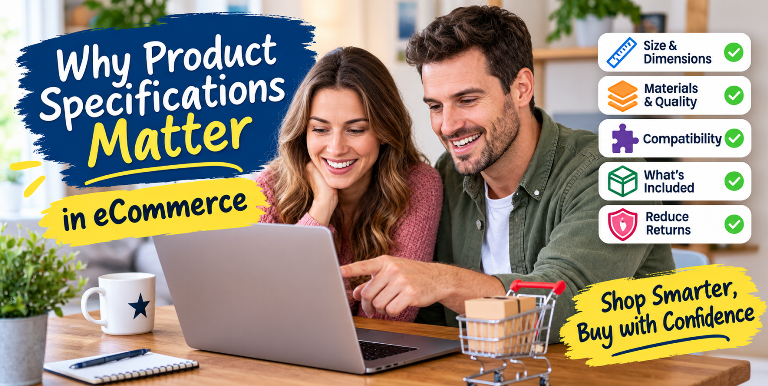
Why Product Specifications Matter in eCommerce
A customer lands on a product page looking for one simple answer: “Will this product work for me?” Sometimes the answer is hidden in a…
Our AI Training Data Services help businesses, technology companies, AI developers, research teams, and organizations prepare structured datasets for machine learning and artificial intelligence applications. We support the collection, organization, annotation, labeling, classification, enrichment, validation, and quality review of data required for developing and improving AI and machine learning models.
Training datasets can include images, text, documents, audio, video, product information, web data, and other forms of structured or unstructured content. Depending on the project, we can prepare datasets for computer vision, natural language processing, speech-related applications, recommendation systems, product intelligence, document understanding, and other AI use cases.
Our workflows can include tasks such as image annotation, object labeling, text classification, sentiment labeling, named entity recognition, document annotation, product categorization, transcription, data segmentation, bounding boxes, polygons, keypoints, and other project-specific annotation requirements. We can work with client-provided datasets as well as data collected from approved sources according to defined requirements.
Each project can be organized around your annotation guidelines, dataset structure, labeling taxonomy, quality standards, and output format. AI-assisted processing can be used where appropriate for repetitive tasks, while human review and validation help identify inconsistencies and improve dataset quality.
Whether you are preparing an initial training dataset, expanding an existing dataset, creating specialized labeled data, or maintaining recurring training data pipelines, our structured approach can support projects of different sizes and data types.
We use a structured workflow to convert raw information into organized and labeled datasets. The process can be adjusted according to the data type, annotation method, model requirements, and quality standards of each project.
Collect and organize relevant data from approved sources based on your project requirements. Data can be gathered according to defined categories, formats, attributes, geographic requirements, or other specifications.
Add labels, tags, classifications, or other annotations to raw datasets so that the information can be used within machine learning workflows.
Prepare visual datasets by identifying and labeling objects, regions, characteristics, and other elements within images according to your annotation guidelines.
Process audio datasets through transcription, segmentation, speaker identification, labeling, and other defined annotation activities for speech and audio-related AI applications.
Annotate video content by identifying objects, actions, events, frames, movements, and other visual elements based on project-specific requirements.
Organize training data into defined categories, classes, labels, or hierarchical structures. Classification can be applied to different data formats depending on the intended machine learning use case.
Label visual information within images according to defined annotation instructions and project requirements.
Create labeled text datasets for natural language processing and language-based AI applications.
Identify and label relevant information within documents, forms, invoices, reports, and other document types.
Divide datasets into meaningful sections, records, objects, frames, or other defined units for subsequent annotation and processing.
Outsourcing repetitive data collection, annotation, labeling, and validation activities can reduce the manual workload for internal AI and data teams.
Defined annotation guidelines and quality processes help maintain consistency across large datasets and multiple batches of training data.
Training datasets can be processed in batches to support projects that require thousands or millions of individual data points, depending on the project scope.
Structured workflows and appropriate AI-assisted methods can help accelerate repetitive preparation and annotation tasks.
Businesses can work with multiple data formats, including images, text, documents, audio, video, and product data, based on their AI project requirements.
Defined labeling rules, taxonomies, and quality checks help create more organized annotation outputs that are easier to review and maintain.
Training data workflows can expand as datasets grow, new product categories are introduced, or AI projects require additional labeled information.
By delegating time-consuming data preparation tasks, internal teams can dedicate more attention to model development, testing, deployment, and other core AI activities.
We proudly work with businesses across diverse industries, delivering reliable, efficient, and customized solutions tailored to their unique needs. Our commitment to quality, innovation, and timely service enables us to build strong, long-term relationships with our clients. From growing businesses to established enterprises, we work closely with every client to understand their challenges, streamline processes, and create solutions that support sustainable growth.
Discover what our clients have to say about their experience with us. From exceptional service to reliable solutions, our commitment to quality has earned the trust of businesses worldwide.
Thanks for your best product entry services and obviously the excellent work on my Magento Store. I am happy and completely satisfied with the increased sale and the way of your company’s work!!! All products looks fantastic and well formatted, I will definitely, no doubt, increase my team size at India-Data-Entry-Services.
USA
Thanks will not enough to justify the work completed by you for our website. I m convince my other friends to use your perfect and professional service as you guys really doing a great job!
Belgium
India-Data-Entry-Services is the only company which works both promptly and professionally. We highly appreciate her great job of our image scanning, OCR and proof-reading work and I would have not any doubt or be the hesitation to definitely use her services in future for our other projects.
USA
India-Data-Entry-Services did the website maintenance for our website and it has result that our website is updated within 24 hours. The excellent team of India-Data-Entry-Services provides the facility for our website of hiding product when it is out of stock, update product when it becomes in stock, online product data entry on ecommerce platform. That’s why I highly recommend IDES for their excellent services.
Germany
India-Data-Entry-Services has a satisfactory service of SEO marketing. Your team is really did a great work on getting us ranked #1 in a very competitive market. Due to the responsible job of yours, our sales almost improved since we started working with you. Thank you very much for your excellent performance.
Australia
I want to say thanks for the catalog designs, you provide. I m really fond of your designs talents and marketing ideas. Thanks for your good job and assistance.
USA
India-Data-Entry-Services is a good company with whom you can do business without any fear of to be cheated. It has a professional team with excellent talent to detail and responsiveness to our web research requirements. Someone who wants a perfect company for an inexpensive quality web research work, I’ll highly recommend IDES.
London
My first experience with India-Data-Entry-Services with outsource data entry was a successful process that I really wants to plan to repeat many times in the future. IDES produced alleviated any concerns I had about whether a company half-way around the globe could meet my data entry needs.
Fiji
Only India-Data-Entry-Services is a single company that make a quick response to our requests and appreciate your willingness to learn our processes and standards. Almost more than 2 year, we are engaged with IDES and from the first few days we have been receiving the fabulous response on our website. It is the result of the great performance of IDES’s hired Full Time Equivalent (FTE) professionals.
USA
My image editing project is continuously going on a good way from the time when India-Data-Entry-Services did a great job with my images. The results are truly effective and have certainly fulfilled my highest expectations. Well done.
Netherland
A customer lands on a product page looking for one simple answer: “Will this product work for me?” Sometimes the answer is hidden in a…
A shopper searches for a pair of running shoes and selects Size: 9, Colour: Black, Brand: Nike.The catalog contains the right products. The website has…
A product catalogue can look perfectly manageable when it contains 200 SKUs.Add another 2,000 products, several variations, multiple sales channels, seasonal collections, supplier updates, and…